Artificial Analysis v5: open weights fall 12 points behind as private benchmarks dominate
Artificial Analysis's v5 index shows open weights models falling further behind, with Kimi K3.1 Pro leading and DeepSeek V4.1 Flash best among released weights. Dean Ball says it is the first AA ranking to match his own model rankings. Nathan Lambert notes private sets can't be trained toward but require trust since bugs go unfound; Zvi Mowshowitz says the change makes more sense now.
All posts · 7, most important first
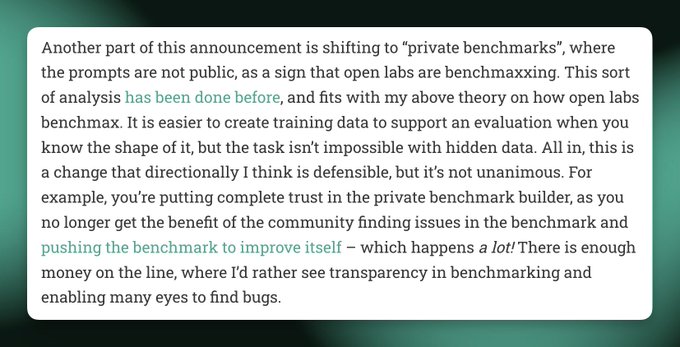
- people train towards private sets, its just more of a guessing game. private sets also require more trust, as the community cant find the bugs that will exist.2 likes · 0 reposts
- This is the first time an Artificial Analysis ranking even roughly approximates my own subjective rankings of models.Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them. The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max). open on X1 likes · 0 reposts
- Okay, this makes so much more sense now.Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them. The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max). open on X6 likes · 0 reposts
- Private benchmarks often show open models are further behind, but the problem with private benchmarks is you don’t have the community to squash the inevitable bugs for you. I'm 50/50 on if I think private or open-source is the best approach.
 19 likes · 1 reposts
- This is the first time an Artificial Analysis ranking has even roughly approximated my own subjective rankings of models.Open weights models fall further behind in v5. The leader, Kimi K3.1 Pro (weights not yet released), scores 46, 12 points behind the leader, compared with a 3-point gap in v4.3. Of models with released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) score highest at 32, and Claude Haiku 5.5 (max) outscores all of them. The gap is widest on HLE-Diamond and Terminal-Bench-Science, where Kimi K3.1 Pro scores 37% and 34%, compared with 68% for Claude Opus 5.5 (max) and 63% for GPT-6 Astra (max). open on X15 likes · 2 reposts
- 1 likes · 0 reposts
- I don’t have as much time to play with new open releases as I used to, but I test drive buzzy new oss releases for at least a few hours on my personal machines/with some of my favorite prompts. Only way to stay sharp in this field is to use as many competing agents as you can. I wouldn’t comment specifically on a new model in depth unless I had a few days to play with it.0 likes · 0 reposts
 @natolambert research ·
 @deanwball policy ·
 @thezvi commentary ·