Kimi K3.1 Pro launches with offensive cyber capability deliberately throttled for open weights
Moonshot's K3.1 Pro blog says its offensive cyber capability was intentionally capped below pipeline and frontier-proprietary levels, after finding cyber content in mid-training data and RL environments lifted vulnerability research during post-training. Weights are due by Nov 4. The model tops open-weight benchmarks and ranks #1 openly available on Artificial Analysis' agentic cyber defense index. Nathan Lambert notes few positive user reactions on the timeline; Peter Wildeford flags interest in cyber, bio, and ECI scores.
All posts · 29, most important first
- Moonshot is intentionally throttling cyber capabilities. From the blog; 'First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes.'
 55 likes · 7 reposts
- Models are are now approaching a massive general jump in cyber capabilities. From the Kimi K3.1 launch post: 'During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially.'
 @andrewcurran_: Moonshot is intentionally throttling cyber capabilities. From the blog; 'First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes.' open on X109 likes · 13 reposts
- Moonshot's Kimi K3.1🇨🇳 open weight model: "K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce." "we aim not to release open weights that would extend the absolute frontier of cyber capability."@andrewcurran_: Moonshot is intentionally throttling cyber capabilities. From the blog; 'First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes.' open on X18 likes · 0 reposts
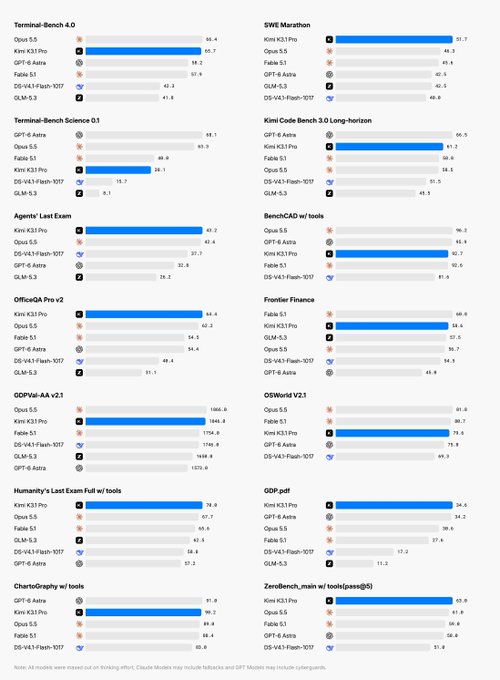
- Kimi K3.1 is announced as 3.1 Pro. The benchmark scores look to be clearly the strongest current open weight model, if the weights are released as they claim by November 4th. They are very impressive scores. The Kimi team makes very clear statements about cyber risks and trying to pace the frontier of open-weight cyber capabilities and moderate it with respect to the closed frontier. Much to be learned in how the model stands up the vibe tests, but in the last few years the Moonshot team has rarely missed with the kimi models. K3.1 is also cheaper than K3 per token, but some benchmarks in the blog show it uses meaningfully more tokens per answer, so it may be about the same price. This, with all the cyber news, and rumors of a bigger GLM model coming soon, sets us up for an exciting rest of the year! The pro name makes me think Kimi will be moving to release flash model soon too, similar to DeepSeek and GLM.
 24 likes · 2 reposts
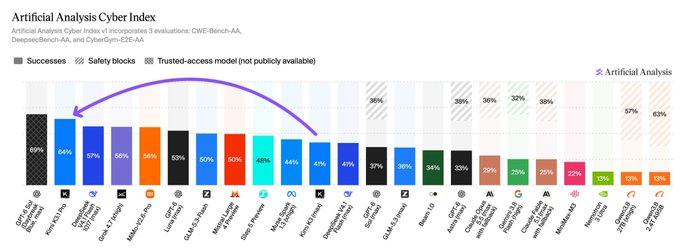 Kimi K3.1 Pro is the new #1 openly-available model for agentic cyber defense, behind only trusted-access model GPT-6 Sol (Daybreak Blue) on the Artificial Analysis Cyber Index @Kimi_Moonshot's Kimi K3.1 Pro scores 64% on the Artificial Analysis Cyber Index, 7 points ahead of the previous leading openly-available model, DeepSeek V4.1 Flash 1017 (57%), and 5 points behind GPT-6 Sol (Daybreak Blue, max, 69%), which is only available through OpenAI's trusted-access program. Once the weights for K3.1 Pro are released, K3.1 Pro will also be the leading open weights model for cyber defense. The Artificial Analysis Cyber Index measures capability on agentic cyber defense tasks and is composed of three benchmarks: CWE-Bench-AA, DeepsecBench-AA and CyberGym-E2E-AA. The Index primarily evaluates models through their publicly accessible APIs, reflecting the cyber capabilities available to developers. Proprietary models from OpenAI, Anthropic and Google may have stronger cyber capabilities but lose points to safety refusals: GPT-6 Sol (Daybreak Blue, max), available through OpenAI's trusted-access program, scores 32 points above its public counterpart. Kimi K3.1 Pro encounters no safety refusals. Key results: ➤ #1 openly-available model and #2 overall: Kimi K3.1 Pro scores 64%, up 23 points from Kimi K3 (41%) and ahead of DeepSeek V4.1 Flash 1017 (57%). Only the trusted-access GPT-6 Sol (Daybreak Blue, max, 69%) scores higher ➤ Highest CyberGym-E2E-AA score of any model: K3.1 Pro scores 95% on CyberGym-E2E-AA, placing it ahead of GPT-6 Sol (Daybreak Blue, 93%) and the next openly-available model, Mistral Large 4 (82%). On DeepsecBench-AA, K3.1 Pro scores 37%, behind GPT-6 Sol (Daybreak Blue, 48%) and GPT-6 Sol (46%). On CWE-Bench-AA it scores 61%, 4 points behind GPT-6 Sol (Daybreak Blue, 65%), with DeepSeek V4.1 Flash 1017 leading at 69% ➤ 15% increase in Cost per Task despite lower token prices: K3.1 Pro has a Cost per Task of $2.81, higher than GPT-6 Sol (Daybreak Blue, max, $1.77) and DeepSeek V4.1 Flash 1017 ($0.42). Kimi K3.1 Pro is 33% cheaper per token than Kimi K3 ($2/$10 vs. $3/$15 per 1M input/output tokens), but uses ~2x more input tokens, resulting in a 15% higher Cost per Task ($2.81 vs. $2.45) open on X0 likes · 0 reposts
- Will be curious to see how well this does on Epoch's ECI score, as well as how well this does on cyber and bio capability. Will also be curious to see how much benefit there is from distillation now that Anthropic has some stronger safeguards (though these safeguards may not yet have had enough time to be effective).Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal. 🔹 Full-project coding: games in Unreal, Unity & Godot. 🔹 Excels at parametric 3D modeling in Blender & CAD. 🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%. 🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks. Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API. Open weights by Nov 4, 2026. 🔗 API: https://t.co/XCrgjXAqMw 🔗 Tech blog: kimi.ai/blog/kimi-k3-1… open on X3 likes · 0 reposts
- Not a lot of positive Kimi 3.1 reactions on the timeline. If you've had time to try the model, what was your impression? (I haven't yet)9 likes · 0 reposts
- hm seems like they forgot to also distill the robot capabilitiesKimi K3.1 Pro scores 9% on real-robot tasks, behind Opus 5.5, Gemini 4 Argon and GPT-6 Astra. open on X10 likes · 2 reposts
- Given this, assume that the publically released models from US frontier labs are also intentionally throttled in this regard, on top of the guardrails. Probably only the unreleased internal models used for R&D and post-training are fully capable.8 likes · 0 reposts
- Full model weights will be released by Nov 4, 2026.0 likes · 0 reposts
- Kimi K3.1 is about to arrive.
 87 likes · 5 reposts
- Kimi K3.1 Pro benchmarks:
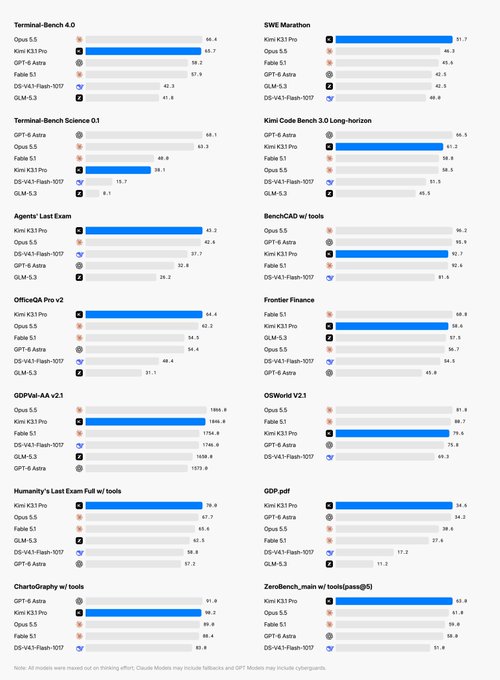 Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model. 🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal. 🔹 Full-project coding: games in Unreal, Unity & Godot. 🔹 Excels at parametric 3D modeling in Blender & CAD. 🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%. 🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks. Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API. Open weights by Nov 4, 2026. 🔗 API: https://t.co/XCrgjXAqMw 🔗 Tech blog: kimi.ai/blog/kimi-k3-1… open on X53 likes · 6 reposts
- Kimi K3.1 Pro is now live for many people, expect benchmarks and release announcement in the next thirty minutes.33 likes · 1 reposts
- Higher score than Fable 5.1 and Astra 6, wild stuff.Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published @Kimi_Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index. Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3. Key results: ➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%. ➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%. ➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower. Additional model details: ➤ Context window: 1M tokens. ➤ Size: 2.8T total, 104B active parameters ➤ Input modalities: Text and image ➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch ➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates. Congratulations to the team at @Kimi_Moonshot on the release! open on X28 likes · 1 reposts
- Monster jump. Passes Astra, Argon and Fable 5.1. This will be open weights in less than two weeks.
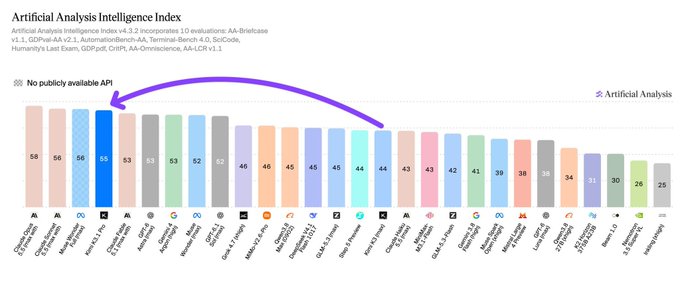 Kimi K3.1 Pro launches at 4th on the Artificial Analysis Intelligence Index scoring 55, making large gains in agentic performance; it will be the leading open-weights model once its weights are published @Kimi_Moonshot's new reasoning model gains 11 points over Kimi K3 (max, 44). It trails only Claude Opus 5.5 (max with fallback, 58), Claude Sonnet 5.5 (max with fallback, 56), and Muse Wonder Full (max, 56) on the Intelligence Index. Once the weights for K3.1 Pro are released it will be the highest-scoring open weights model and the gap between the leading open weights and proprietary models on the Intelligence Index will narrow from 12 points to 3. Key results: ➤ Large gains in agentic performance: Kimi K3.1 Pro scores 3rd on GDPval-AA with 1,846 Elo, up 312 Elo from Kimi K3, behind only Claude Opus 5.5 (1,866 Elo) and Muse Wonder Full (1,857 Elo). Kimi K3.1 Pro also achieves the highest score of any model on Terminal-Bench 4.0. K3.1 Pro scores 67%, up from 13% for Kimi K3 and ahead of Claude Sonnet 5.5 (64%). AutomationBench-AA, which tests agentic SaaS workflows, rises from 58% to 73%. ➤ Gains in other evals are more moderate: Humanity's Last Exam rises from 47% to 52%, CritPt from 23% to 25%, and SciCode from 59% to 61%. AA-Omniscience Index rises from 20 to 30, as the hallucination rate falls from 53% to 44% and accuracy rises from 48% to 51%. ➤ Cost per Task roughly equal to Kimi K3 at $1.98 per Task: K3.1 Pro uses 55K output tokens per Intelligence Index task, 14% more than Kimi K3 at 48K, while its first-party token prices are 33% lower. Additional model details: ➤ Context window: 1M tokens. ➤ Size: 2.8T total, 104B active parameters ➤ Input modalities: Text and image ➤ Weights and license: Weights currently not published, Moonshot is expected to release the weights soon after launch ➤ Pricing: $2/$10/$0.20 per 1M input/output/cache hit tokens, 33% lower than Kimi K3 on all three rates. Congratulations to the team at @Kimi_Moonshot on the release! open on X28 likes · 2 reposts
- It appears to be very impressive.14 likes · 1 reposts
- From the blog:
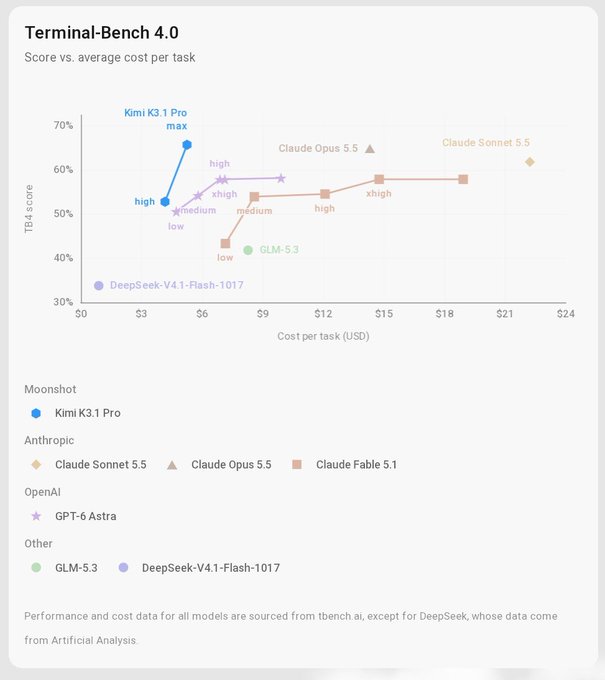 8 likes · 0 reposts
- Pricing.
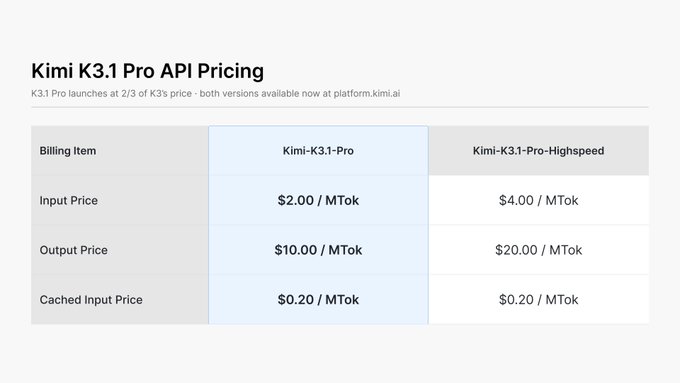 7 likes · 0 reposts
- TLDR on the kimi k3.1 pro benchmarks is that it looks like they figured out their RL, where the initial release was a very impressive base model with lighter post-training. China is very much keeping pace with capability gains.6 likes · 0 reposts
- Official:@andrewcurran_: Kimi K3.1 Pro benchmarks: open on X4 likes · 0 reposts
- 4 likes · 1 reposts
- Another:K3.1 Pro by @Kimi_Moonshot on KingBench 4. Leaving openness aside, This is a bad model. It scores the 6th position with 53.7% and costs $31.88 which is jut $16 cheaper than Opus. You can get better results than this with Haiku or Sol for like $25 cheaper. The whole pitch of cheap looks like BS right now. The model constantly re-reads cache and costs way more than most models and it also under-performs on my bench. It seems that they found out a way to make a model cost more by basically making it read caches more often to recover their costs (which is also why cache reads cost the same as Opus). In no way will I tell anyone to use it.. The cost to performance is really bad. open on X2 likes · 0 reposts
- Is this a 3D model?2 likes · 0 reposts
- Makes sense; many such benchmarks!Kimi K3.1 Pro scores 9% on real-robot tasks, behind Opus 5.5, Gemini 4 Argon and GPT-6 Astra. open on X1 likes · 0 reposts
- They are intentionally throttling some capabilities for the open-weights release:@andrewcurran_: Models are are now approaching a massive general jump in cyber capabilities. From the Kimi K3.1 launch post: 'During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially.' open on X1 likes · 0 reposts
- Not live for me yet either.1 likes · 0 reposts
- GPT-5.6-sol, which was previewed on June 26, scores 14.9% on RoboDojo; If you believe that Chinese models are six months behind American ones, you would expect Kimi K3.1 Pro to do a bit worse than that, and it does! (Would want to see the new Deepseek Flash results though)Kimi K3.1 Pro scores 9% on real-robot tasks, behind Opus 5.5, Gemini 4 Argon and GPT-6 Astra. open on X0 likes · 0 reposts
- Examplerandom data point: kimi k3.1 pro is markedly worse at accessing niche details about twitter anons (no tools) than kimi k3 but it reads to me more like an unwillingness to take risks than necessarily lacking the information, and can sometimes be prompted to recall more. open on X0 likes · 0 reposts
- congrats!0 likes · 0 reposts
 @andrewcurran_ commentary ·
 @peterwildeford policy ·
 @natolambert research ·
 @tim_hua_ research ·